SAR舰船检测数据集SSDD和LS-SSDD的训练集和检测集划分代码
SSDD数据集简介与划分
SAR舰船检测数据集SSDD(SAR Ship Detection Dataset) 可以说是比较经典的数据集了,在 SAR Ship Detection Dataset (SSDD): Official Release and Comprehensive Data Analysis 里有这样一段话
The images with the last digits of the file number 1 and 9 are uniquely determined as the test set, and the rest are regarded as the training set. Such a rule can also maintain the distribution consistency of the training set and test set, which is conducive to network feature learning.
大致翻译一下,就是文件编号为1和9的最后一位的图像被严格确定为测试集,其余图像被视为训练集(本人注释:包括验证集)。这样的规则还可以保持训练集和测试集分布的一致性,有利于网络特征学习。
毕竟样本太少了,只有1160个,随机划分可能会破坏训练集和测试集之间的分布一致性,导致结果不一样。而且,对于每一个样本都是十分珍贵的。但是对于训练集和验证集的划分,论文并没有给出明确的规定。但是给出了一个建议是建立交叉验证集。这里我是给出了尾号8作为验证集,这样验证集中就包括了近岸和远海目标。
所以写了个脚本分一下训练集和检测集。
suffix_1 = list(range(1,1160,10))
suffix_9 = list(range(9,1160,10))
suffix_8 = list(range(8,1160,10)) # 验证集不想用尾号8可以改
suffix_1_9 = suffix_1+suffix_9
suffix_1_9.sort()
#-----------------------test---------------------#
test = [str(i).zfill(6) for i in suffix_1_9]

with open("ImageSets/Main/test.txt", 'w') as f:
    for i in test:
        f.write(i+'\n')
#-------------------train&val--------------------#
suf_not_1_9 = []

for i in list(range(1,1161)):
    if i not in suffix_1_9:
        suf_not_1_9.append(i)

trainval = [str(i).zfill(6) for i in suf_not_1_9]

with open("ImageSets/Main/trainval.txt", 'w') as f:
    for i in trainval:
        f.write(i+'\n')
#-----------------val----------------------------#
val = [str(i).zfill(6) for i in suffix_8]

with open("ImageSets/Main/val.txt", 'w') as f:
    for i in val:
        f.write(i+'\n')
#-----------------train--------------------------#
suf_not_1_8_9 = []

for i in suf_not_1_9:
    if i not in suffix_8:
        suf_not_1_8_9.append(i)

train = [str(i).zfill(6) for i in suf_not_1_8_9]

with open("ImageSets/Main/train.txt", 'w') as f:
    for i in train:
        f.write(i+'\n')
LS-SSDD数据集简介与划分
SSDD虽然经典,但是样本太少了,所以论文 LS-SSDD-v1.0: A Deep Learning Dataset Dedicated to Small Ship Detection from Large-Scale Sentinel-1 SAR Images 给出了一个新的数据集LS-SSDD,这个数据集特点是大尺度影像小舰船检测。由15张24,000×16,000大图以及9,000张分割好的800x800小图组成。文件目录如下图所示。
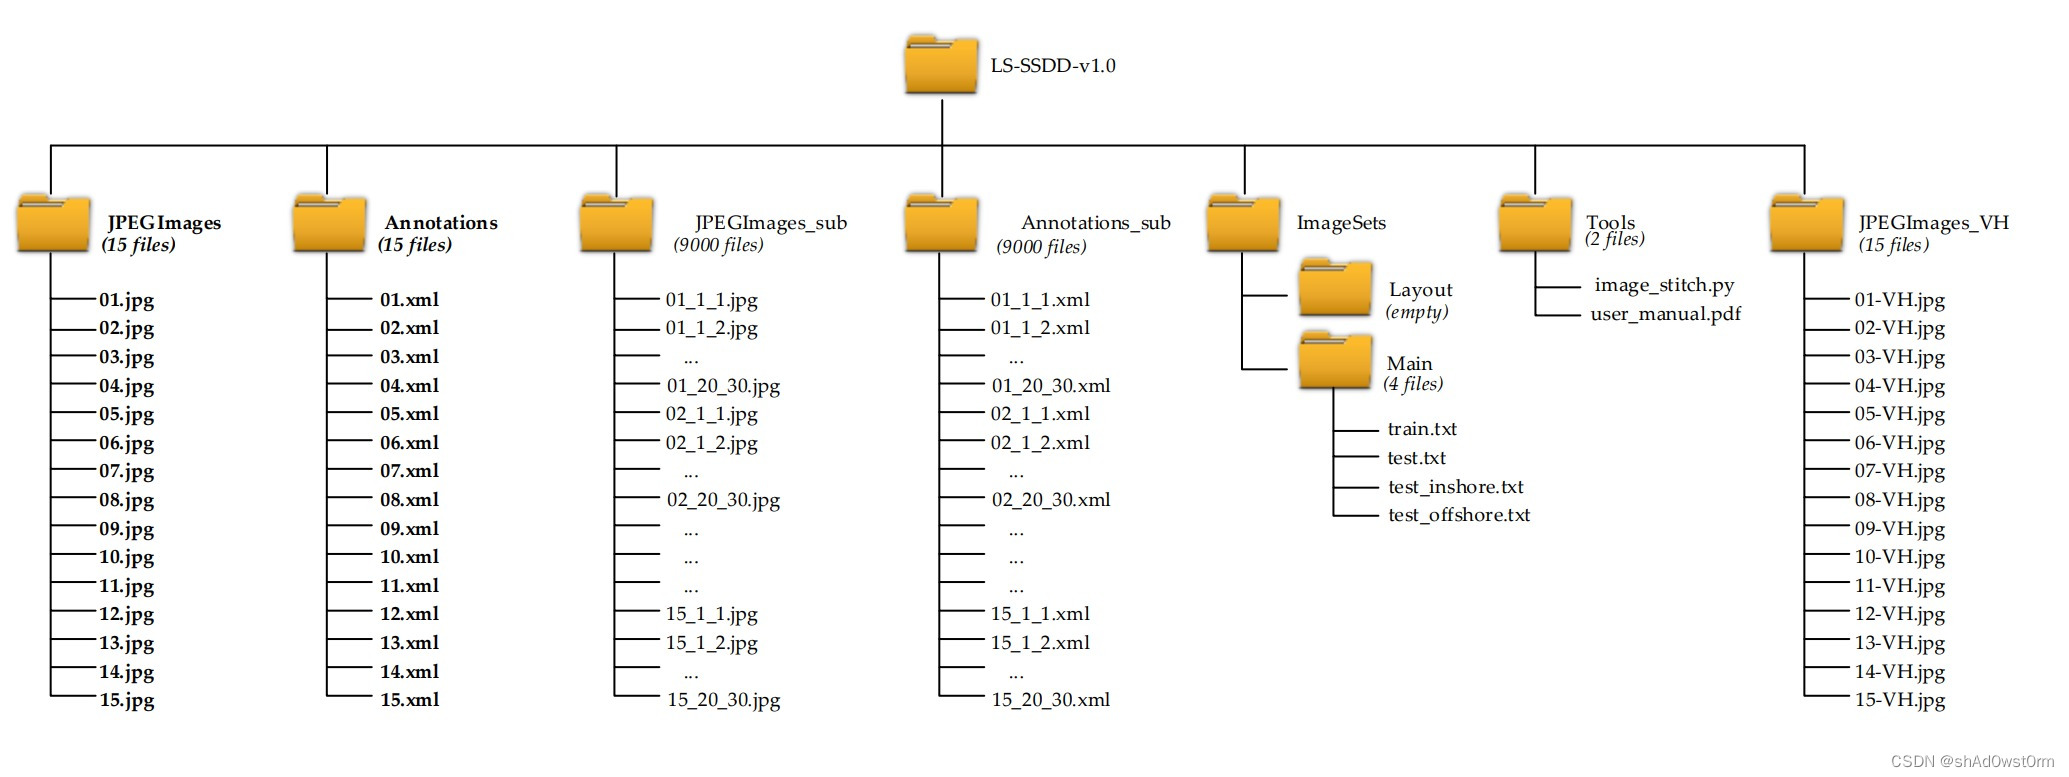 需要注意的是,在ImageSets文件夹中不光给出了训练集和测试集的划分,还给出了专门的近岸(test_inshore.txt)和离岸(test_offshore.txt)测试数据集的划分。便于研究者进行专门的研究。
之前有单独用过里面的近岸测试集进行模型的泛化性分析,所以需要提取一下数据集,这里给出代码,有需要就用。
# 本脚本用来将ImageSets中的训练集,测试集,近海岸测试集,离岸测试集中影像分别提出
import os,shutil

#shutil.copyfile应用,参数必须具体到文件名
def mycopyfile(srcfile,dstfile):
     if not os.path.isfile(srcfile):
        print("%s not exit!" % (srcfile))
     else:
        fpath,fname=os.path.split(dstfile)
     if not os.path.exists(fpath):
        os.makedirs(fpath)
     shutil.copyfile(srcfile,dstfile)
     #print("copy %s" % (srcfile,dstfile))

with open("ImageSets/Main/test.txt", "r") as f: # 需要什么数据集就引入
    dir = f.read().splitlines()

# mycopyfile(srcfile,dstfile)

for i in dir :
    src_img_file = 'JPEGImages_sub/' + i + '.jpg'
    dst_img_file = 'TestSets/test/JPEGImages/' + i + '.jpg'
    src_anno_dir = 'Annotations_sub/' + i + '.xml'
    dst_anno_dir = 'TestSets/test/Annotations/' + i + '.xml'
    mycopyfile(src_anno_dir, dst_anno_dir)
    mycopyfile(src_img_file, dst_img_file)